
Developer — AI for developers
Agentic CLI customizations now in the usage metrics API
GitHub Copilot expands existing CLI report coverage with agentic activity metrics for skills, custom agents, Model Context Protocol (MCP) servers,…

Claude Code relaunches Projects to manage multiple AI agents in the cloud
The revamped projects feature in Claude Code allows users to run multiple agents under the same roof, with a shared memory, goals, and library of…

Anthropic’s new Claude Code feature could drain your plan before lunch
Anthropic is giving Claude Code a new job: Manage other Claude Code sessions. Starting Thursday, Anthropic says select Claude Pro
Migrating the GitHub Copilot runtime to Rust, using Copilot
A rewrite this size wasn't affordable before agents. Here's what porting the Copilot agent runtime to 800,000 lines of production Rust actually took.
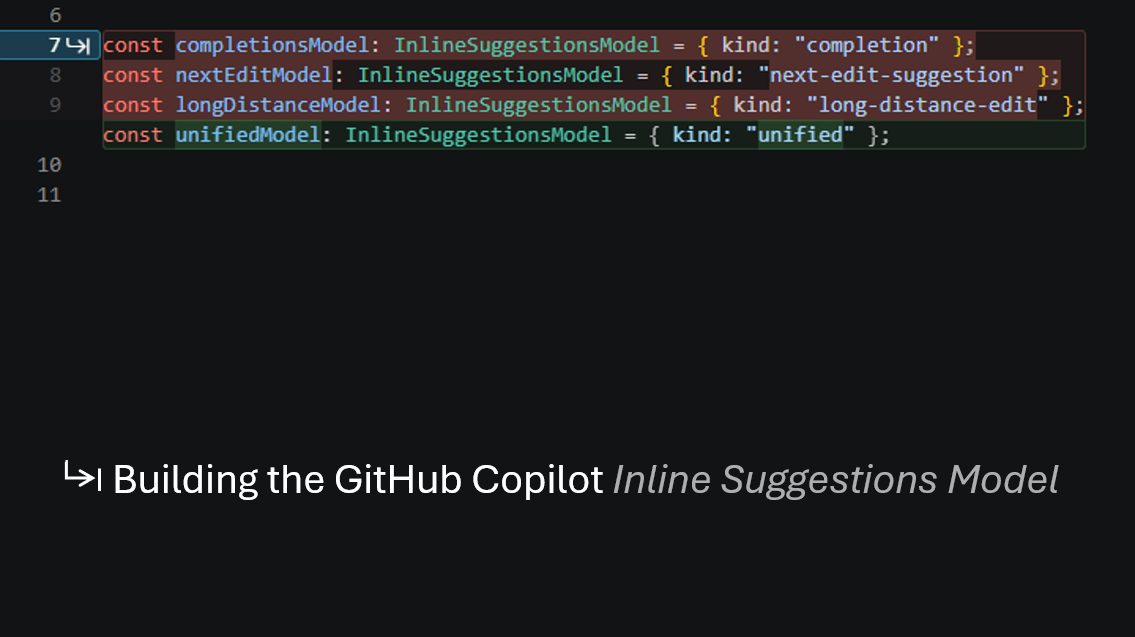
Building the new GitHub Copilot Inline Suggestions Model: Part One
Explore how GitHub Copilot unified completion, next edit, and long-distance suggestions into one model for a faster, more cohesive coding experience.
 Illustration
Cognition helps Devin test its own work with GPT‑6 Astra
GPT‑6 Astra improves Devin’s ability to test software and show that it works, with the goal of helping engineers review less code and ship more.
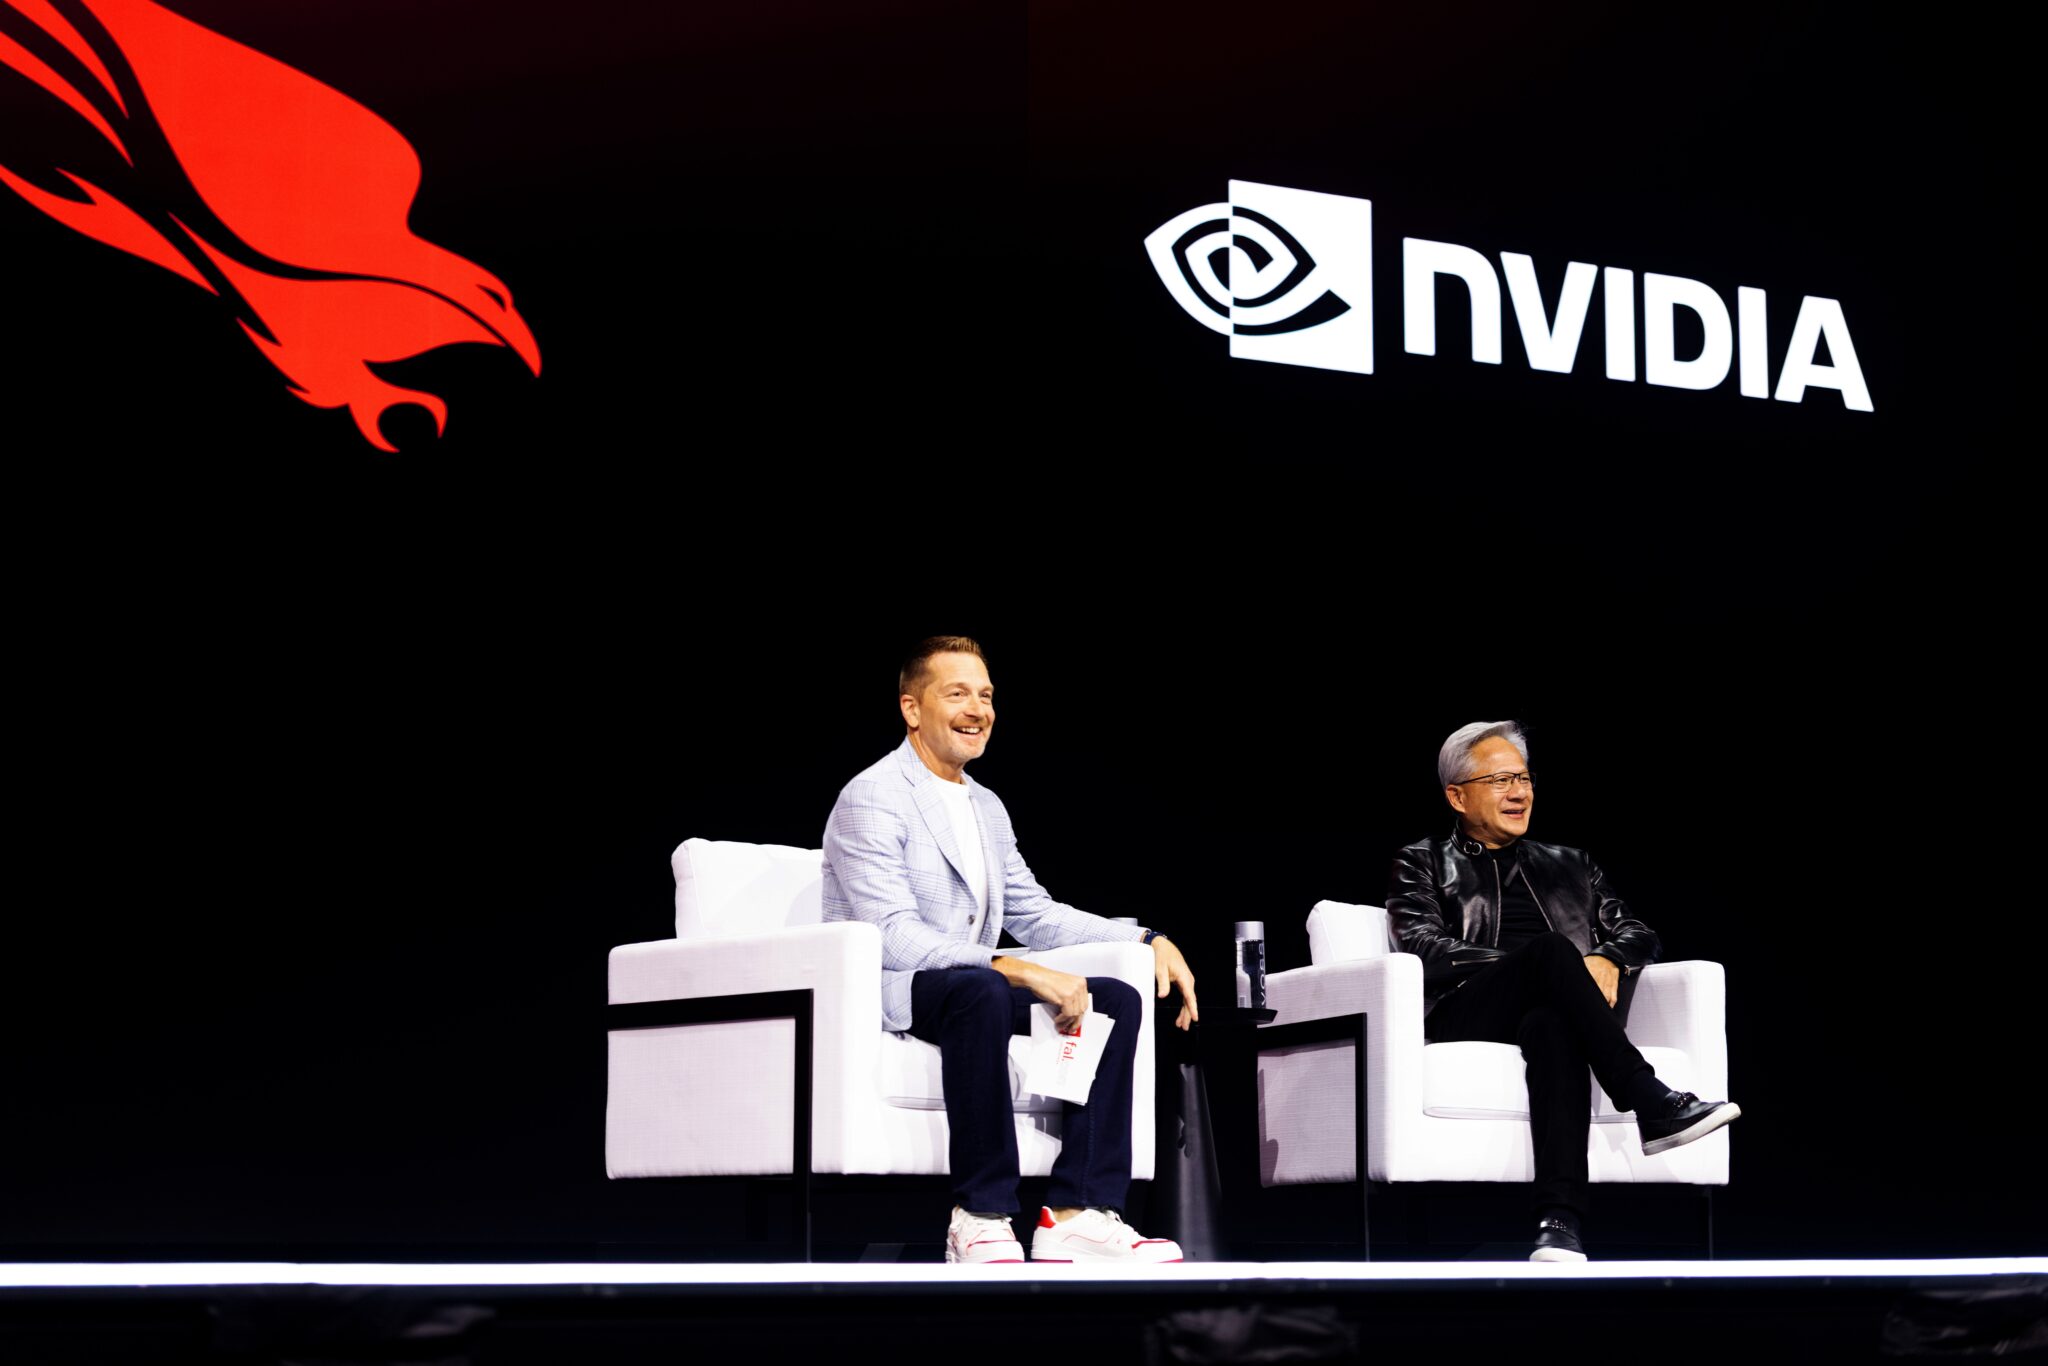
NVIDIA and CrowdStrike Strengthen Agentic Cybersecurity Frontier
“We’re at an inflection point in cybersecurity,” Jensen Huang told a sold-out crowd at CrowdStrike’s Fal.Con 2026 in Las Vegas Tuesday.
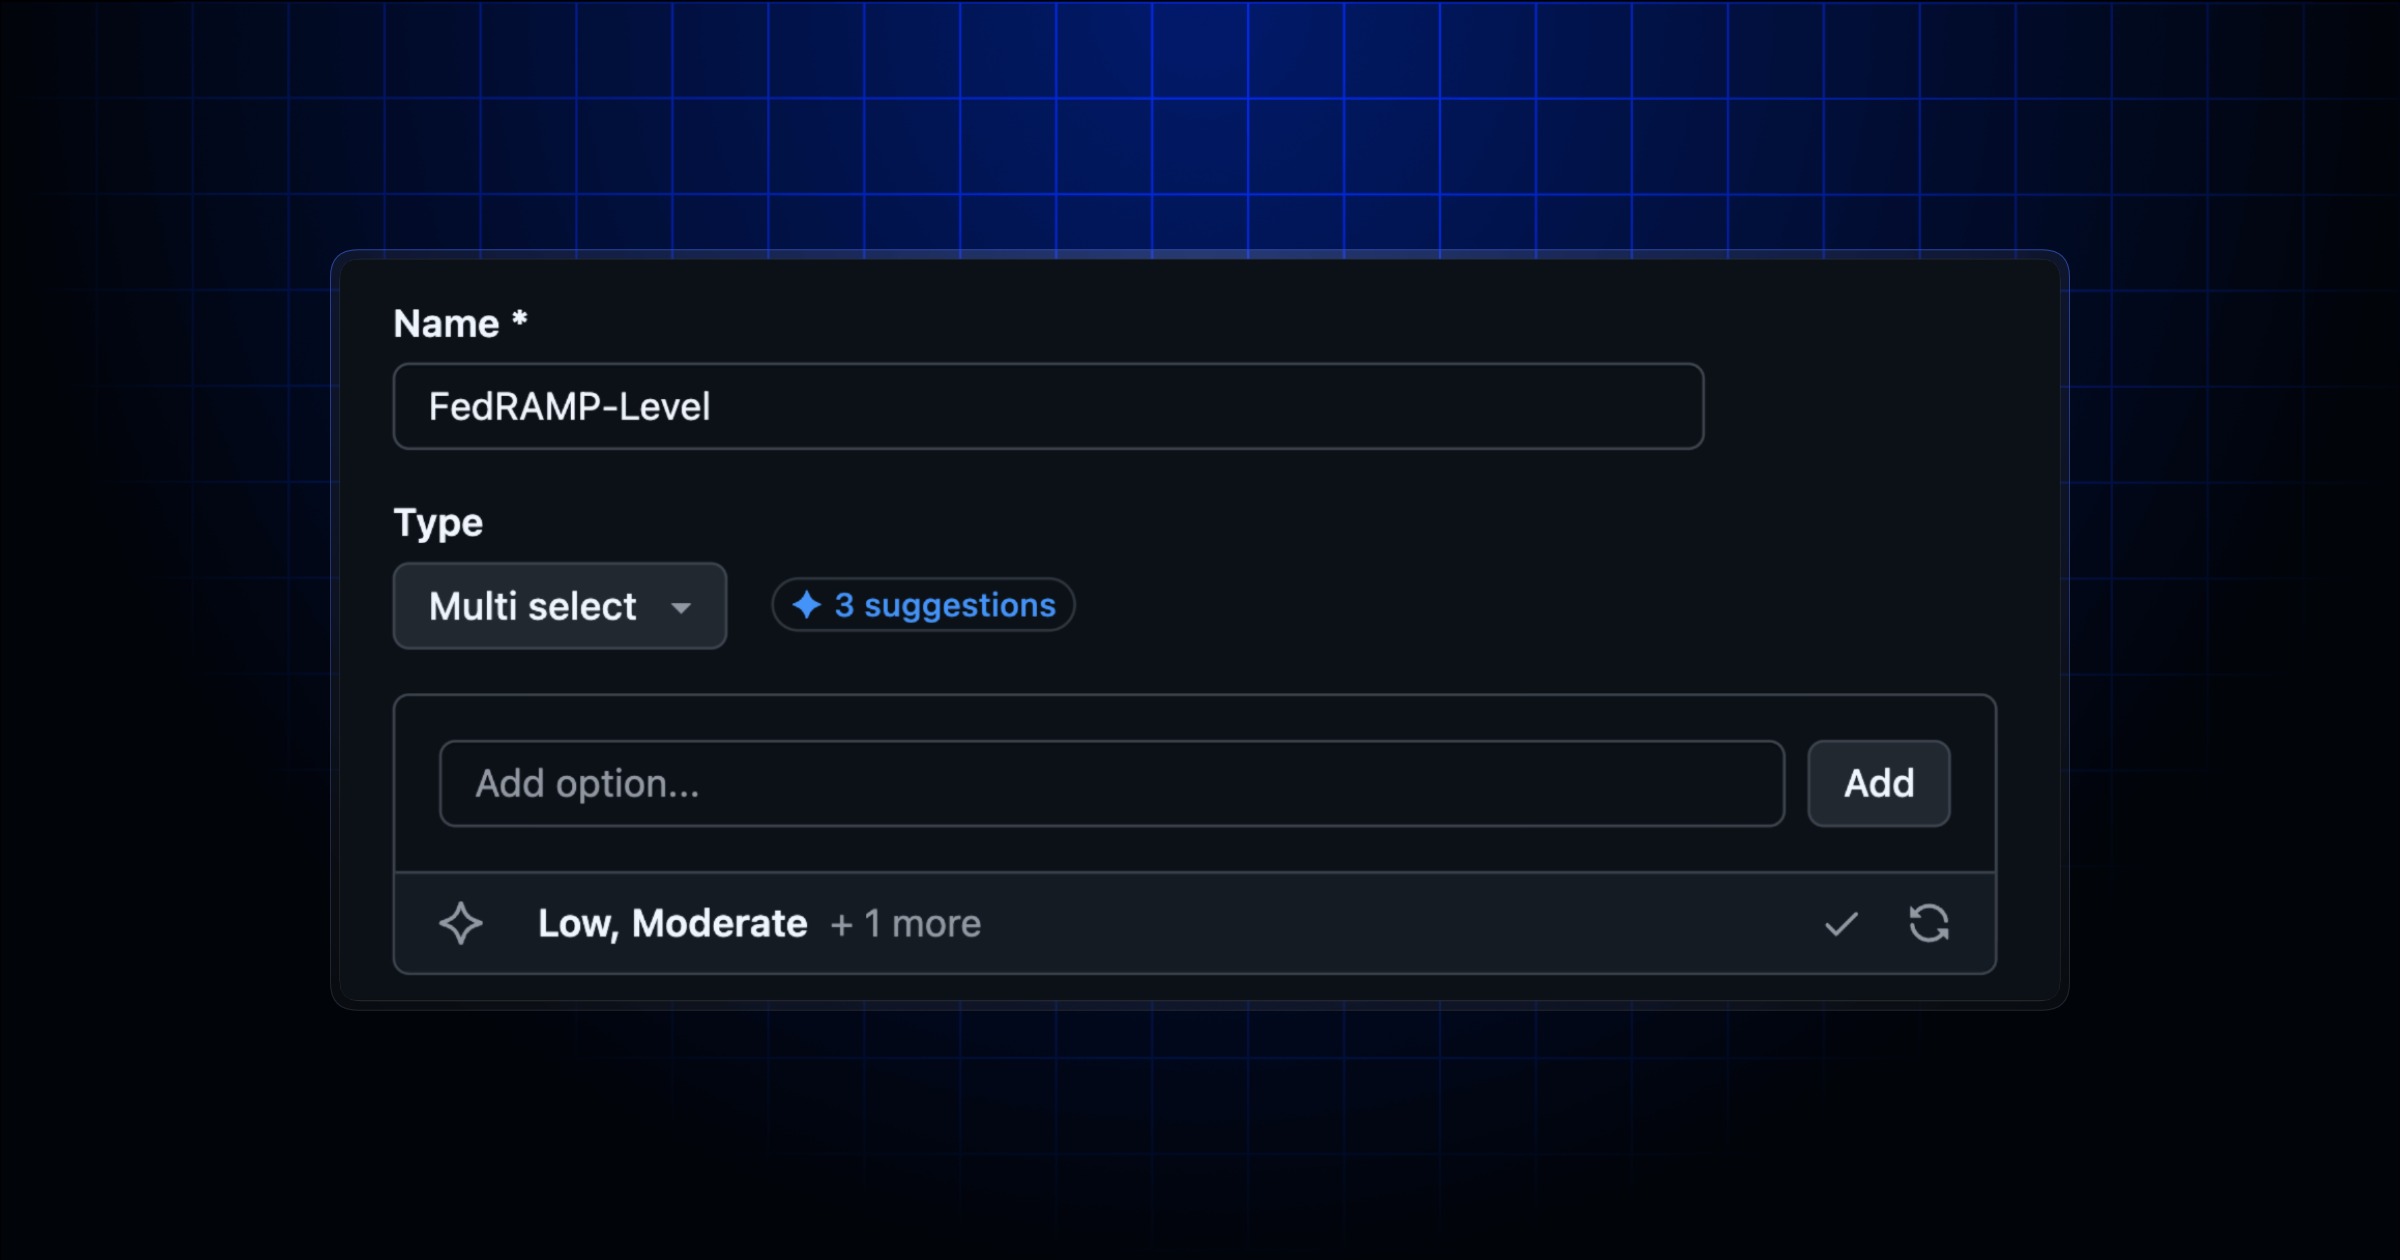
GitHub Copilot suggests custom properties definitions
GitHub Copilot can now suggest allowed values when you create a custom property for repositories in your organization.
GitHub Copilot app for Beginners: Using the diff, terminal, and browser
Checking agent-generated code usually means hopping between tabs. Learn how to view diffs, run terminal commands, and preview web apps side by side…
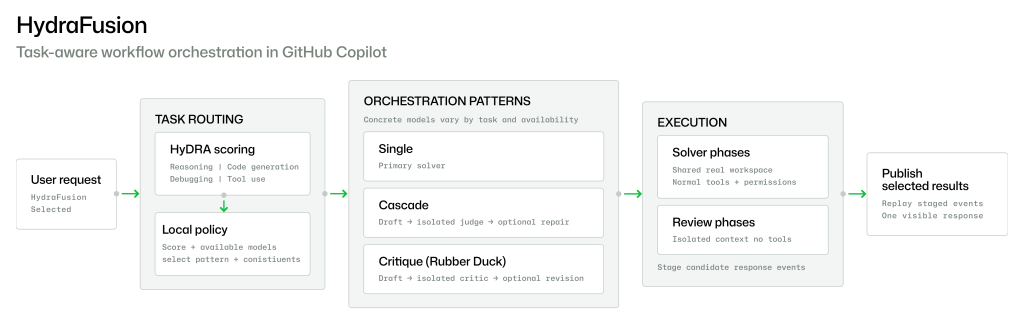
Project HydraFusion: Frontier quality via multi-model orchestration
In controlled offline evaluations, HydraFusion’s selective coding workflows matched or exceeded the evaluated Opus 5 baseline while reducing…
GitHub Copilot app for Beginners: Run several agents at once
Learn how to run parallel agents in the GitHub Copilot app, and experience the moment it stops feeling scary and starts feeling powerful.
GitHub Copilot app for Beginners: Automate Dependabot pull request triage
Managing library updates can be tedious at times. Learn how the GitHub Copilot app can handle this type of repetitive task.
 Illustration
Java’s age is its AI superpower
Ryan welcomes Markus Eisele to the program to talk about why your coding agent should be writing Java.
 Illustration
How to build a secure-by-default AI coding agent
Ryan chats with Greg Jennings, VP of Engineering for AI Products at Anaconda, about what it takes to build a secure-by-default AI coding agent, why…
IllustrationInside LinkedIn's cognitive memory agent for agentic personalization
Ryan is joined by Praveen Bodigutla, Principal AI Researcher at LinkedIn, to chat about the four-layer memory system his team built to give…
Dispatches from O'Reilly: The right amount of spec for agentic development
When code gets cheap, the hard part is deciding what “correct” means and building a reliable way to check it.
From PHP to team lead of agents: rethinking judgment, review, and data with Google's Andi Gutmans (Part 1)
Andi Gutmans, head of Agentic Data Cloud at Google and co-creator of PHP, joins Leaders of Code to talk about why agentic development feels less like…

Meta lets Claude and Codex configure WhatsApp Business via MCP. But the agents don’t get their own identity.
Any business worth its salt in 2026 needs to be embracing the right tools to reach its customers, and few

AI’s best coding agent fails 60% of the time — and the data backs it up
Claude Fable 5.1 just won a new coding benchmark despite failing more than six out of 10 times. Its 38.8%
IllustrationIntroducing the Agents API
Build and launch cloud agents with the Agents API, a managed service powered by the Codex harness for orchestration, long-running sessions, and tool…
 European Commission - Photographer: Aurore Martignoni · CC BY 4.0 · Wikimedia Commons · illustrative
Our decision on Cursor following its acquisition by SpaceX
Our decision to wind down our contract providing OpenAI models to Cursor following its acquisition by SpaceX.
 Illustration
NeMo Data Designer: An Extensible Framework for Multimodal Synthetic Data Generation
We present NeMo Data Designer (NDD), an open-source, general-purpose framework for multi-modal synthetic data generation (SDG).
IllustrationFairCompressAgent: An Agentic Framework for Fairness-Aware Model Compression for FPGA Deployment
Fairness-aware model compression requires selecting methods and configurations that balance accuracy, fairness, and deployment cost.
 Illustration
TuiML: Machine Learning for AI Agents
Machine-learning libraries such as Weka and scikit-learn were designed for human programmers.
 Illustration
Designing Agentic AI Workflow Portfolios under Imperfect Selection and Compute Cost
Agentic AI systems often approach the same task through multiple workflows that differ in reasoning strategy, verification structure, and compute…
 Illustration
WFM: Wiki Foundation Model for Complex Agentic Reasoning
Real-world agents fundamentally require persistent non-parametric knowledge for dynamic reasoning, i.e., long-term memory and retrieval-augmented…
IllustrationCompositional Policy Violations: When Step-Level Compliance Fails In Agentic AI Workflows
Agentic workflows now make consequential decisions in regulated settings, and the governance placed around them is almost entirely step-scoped:…
IllustrationReflections on Trusting Trust, Revisited: Contaminating Self-Modifying AI Coding Agents with Poisoned Benchmarks
Thompson's "Reflections on Trusting Trust" showed that a compiler can be poisoned to reinsert its own backdoor, so that even recompiling clean source…
 Illustration
An Empirical Evaluation of Cost-Efficient Large Language Models on Algorithmic Programming Tasks
This study empirically evaluates whether cost-efficient Large Language Models (LLMs) can be trusted to generate enterprise code to a written…
 Illustration
Semantic CSI Feedback for Beam Selection: When Task-Aware Embeddings from Sparse Pilots Outperform Full-Bandwidth Reconstruction
Classical CSI feedback in FDD massive MIMO transmits a compressed reconstruction of the channel, optimizing fidelity to the original signal…
IllustrationVoiceTrace: A Benchmark and Retrieval Framework for Who-Said-What Speech Retrieval
Speech retrieval has become increasingly important as spoken content continues to grow across meetings, lectures, podcasts, and videos.
 Illustration
MCPAgentBench: A Real-world Task Benchmark for Evaluating LLM Agent MCP Tool Use
Large Language Models (LLMs) are increasingly serving as autonomous agents, and their utilization of external tools via the Model Context Protocol…
 Illustration
AMIGO: Agentic Multi-Image Grounding Oracle Benchmark
-cross Abstract: Agentic vision-language models increasingly act through extended interactions, but most evaluations still focus on single-image,…
 Illustration
Libra: Efficient Resource Management for Agentic RL Post-Training
-cross Abstract: Reinforcement learning (RL) has emerged as a standard post-training paradigm for shaping large language models (LLMs) into capable…
 Illustration
Agentic Real2Sim: Physics-based World Modeling with Vision-Language Agents
-cross Abstract: Real-to-sim conversion for robotic interaction with objects remains labor-intensive because it requires more than visual…
IllustrationGoverning Agentic AI in FinTech
-cross Abstract: Financial institutions are delegating consequential decisions to agentic AI systems that decompose goals, coordinate models and…
IllustrationM-SQE: Multilingual Skill Quality Estimation for Enhancing Language Equality in Agentic Skill Use
Agent skills, reusable procedural documents that extend LLM agents beyond their parametric memory, have become an important interface for deploying…
IllustrationBeyond frequency measures: Can contextual embeddings capture meaning change in scientific texts?
Identifying technological trends is a core scientometric task, yet traditional frequency-based approaches struggle to capture substantial meaning…
IllustrationAgentPack: A Dataset of Code Changes, Co-Authored by Agents and Humans
-cross Abstract: Fine-tuning large language models for code editing has typically relied on mining commits and pull requests.
 Illustration
Compiled Agency: Frontier General-Purpose Coding Agents Build Winning Game Players from Bare Interaction - from Flappy Bird to StarCraft II and Civilization
LLM agents have repeatedly struggled to convert knowledge of a game into competent play, even when researchers build the agent around the model -…
IllustrationAgora: Git as Shared Memory for Collective AutoResearch
Autonomous research loops such as AutoResearch show that one coding agent can improve a training setup unattended.
 Illustration
PentestChain: A Cost-Aware, MCP-Orchestrated Framework for Automated Penetration Testing with Free-Tier LLMs
AI-driven penetration testing has been demonstrated with premium frontier models such as GPT-4, but the per-engagement token cost makes continuous,…
IllustrationQuanta: A Self-Contained Python Library for Hybrid Retrieval over Quantised Embeddings, Lexical Indexes, and Knowledge Graphs
An advanced retrieval-augmented generation pipeline is typically assembled from three or four independently operated systems: an approximate…
IllustrationNeuroECG: ECGFounder-Based Deep ECG Representation for EEG-Free Neurological Prognostication After Cardiac Arrest
Neurological prognostication after cardiac arrest commonly relies on electroencephalography (EEG). However, EEG demands high clinical resources.
IllustrationAn Agentic Framework for Neuro-Symbolic Programming
Integrating symbolic constraints into deep learning models could make them more robust, interpretable, and data-efficient.
 Illustration
FrogNano: Training a 4B Coding Agent via Online Task Synthesis
We present FrogNano, a 4B coding agent designed to tackle software engineering (SWE) tasks efficiently and effectively, even under…
IllustrationEvaluating Context Segmentation in Locally Deployable SLMs for Cybersecurity CTF Tasks
-cross Abstract: The proliferation of highly capable open-weight Small Language Models (SLMs) democratizes access to advanced cybersecurity…